At a glance
V4 Agent — most accurate
V4 writes and runs code to complete long, multi-step browser tasks. It can research across many pages, compare options, follow detailed instructions, collect records, and save the results as a spreadsheet or in any format. Best for:- Bulk data collection
- Complex tasks that span many pages and sites
- Long, difficult instructions
- “Collect every document with its title, reference, and deadline.”
- “Create a spreadsheet of all the pricing plans across these five competitors.”
V3 Agent — fastest
V3 looks at the page and acts step-by-step like a human would. In this evaluation, it was the fastest and less accurate than V4. Best for:- Simple tasks, such as finding publicly available information
- Workloads where speed is essential
- Open-ended research
- “Get a shipping quote for a 3 lb package between two zip codes.”
- “Check whether this product is in stock and what it costs right now.”
V2 Agent — first generation
V2 is based on the open-source agent architecture. In this evaluation it was less accurate than V3 and V4.V4 completes the hardest tasks
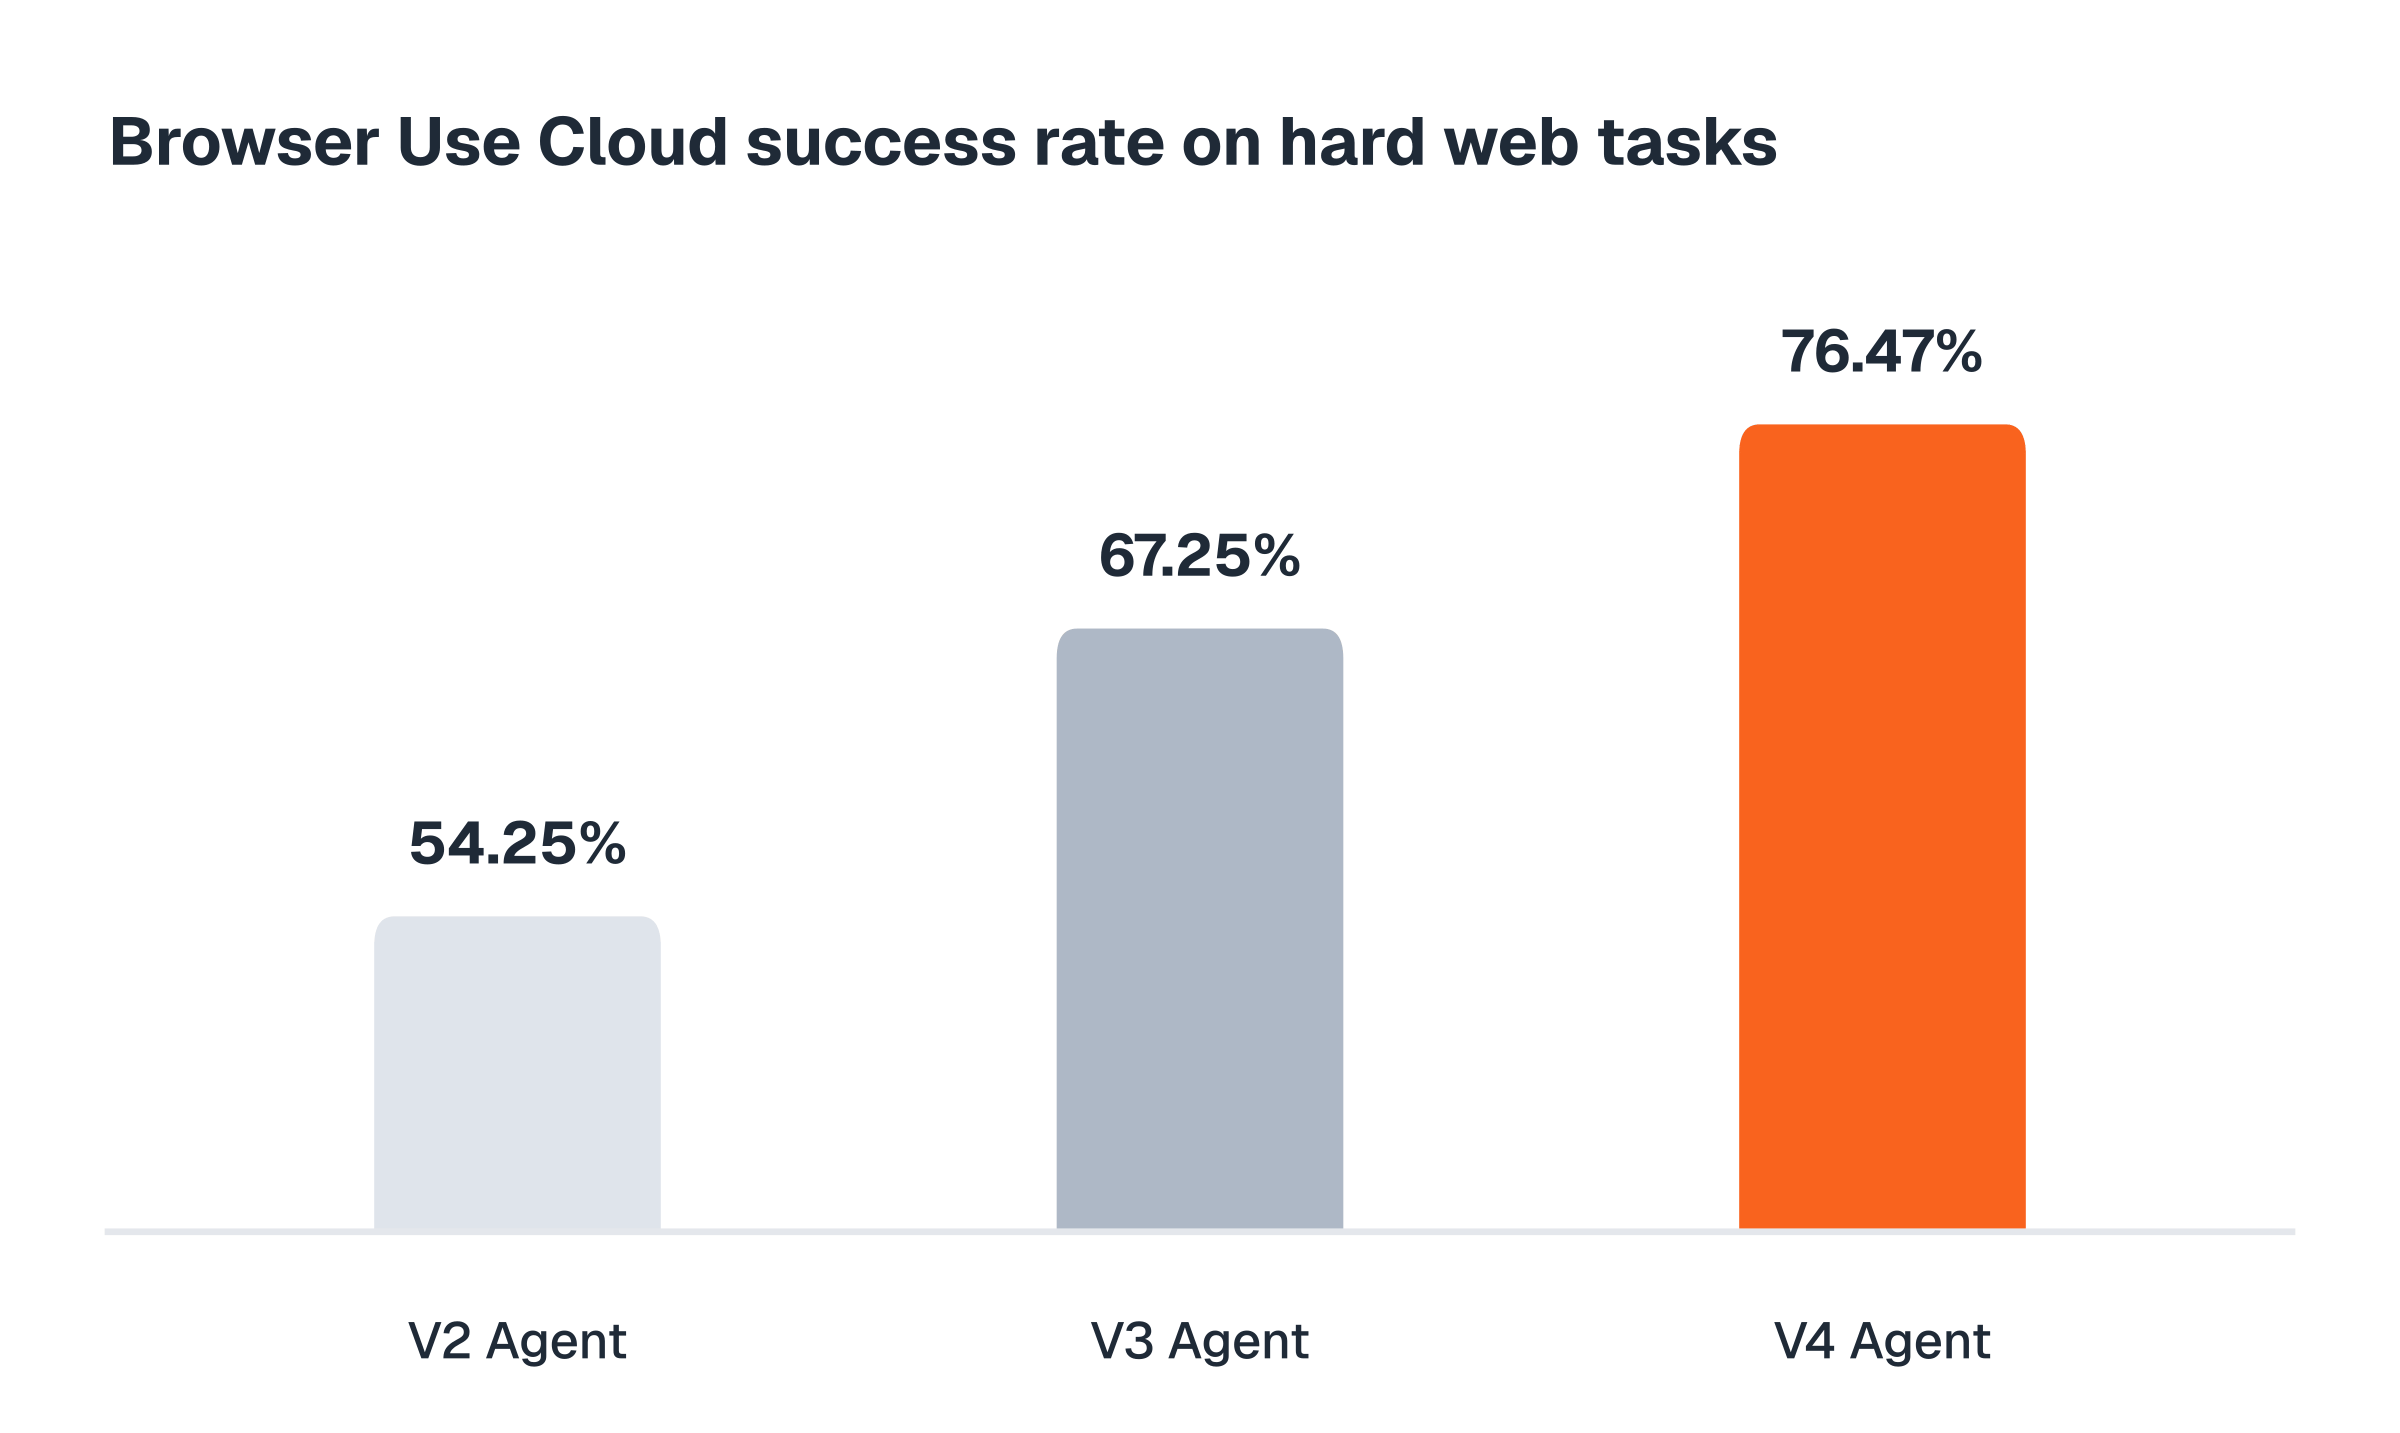
V4 completed 76% of difficult, real-world browser tasks — nine points ahead of V3 and twenty-two ahead of V2.